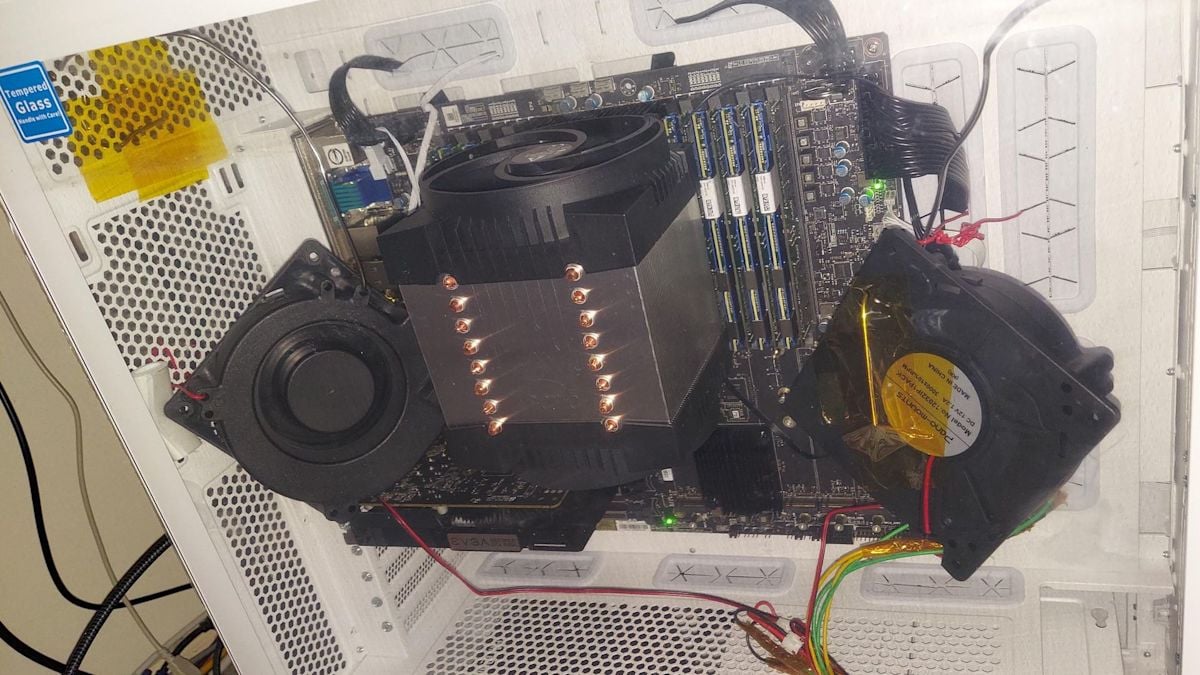
More control over where the model’s tensors are located,
said u/APFrisco, describing a hardware solution that makes massive AI models accessible to standard server rigs.
A hardware enthusiast has deployed a 2.8-trillion-parameter AI model using discontinued Intel Optane memory sticks and a server CPU instead of a GPU, according to Sweclockers.
Running Kimi K3 on Discontinued Hardware
The build runs Moonshot AI’s Kimi K3 model on a 40-core third-generation Xeon Scalable processor. Because the model requires a data center inference engine and at least 610 gigabytes of RAM to function, the builder utilized second-generation Optane Persistent Memory 200 Series modules to reach that capacity at a fraction of standard DRAM costs. The project follows a separate user’s first-generation Optane experiment earlier in the year.
Intel PMem 200 Offers Higher Bandwidth in App Direct Mode
Intel launched the PMem 200 lineup in 2020 to support its third-generation Xeon Scalable platforms in 128GB, 256GB, and 512GB capacities, offering higher effective speeds and up to 32 percent higher memory bandwidth than first-generation hardware on two-socket platforms.
Running in App Direct Mode—which exposes the hardware as a separate, persistent region that software maps directly, differing from Memory Mode where Optane acts as system memory with DRAM as a cache—the system gives the builder mer kontroll över var modellens tensorer finns,
as noted by the creator of the first build, u/APFrisco, and covered by Yahoo.
Low Quantization Speeds Meet High Thermal Limits and eBay Bargains
Performance sits at 0.75 tokens per second when utilizing 3-bit quantization, dropping under 1-bit quantization, according to Yahoo. These pre-tuning numbers leave room for future optimization by adjusting thread counts or NUMA affinity. Sweclockers noted that individual 128GB DCPMM modules can be found on eBay for around 1,800 kronor, providing a much lower price per GB than traditional DDR memory.
The intensive CPU-only workload generates severe heat, with each Optane module drawing significant power and getting extremely hot during sustained inference. Thermal throttling begins at 83 degrees Celsius, and a hard shutdown occurs at 85 degrees Celsius.