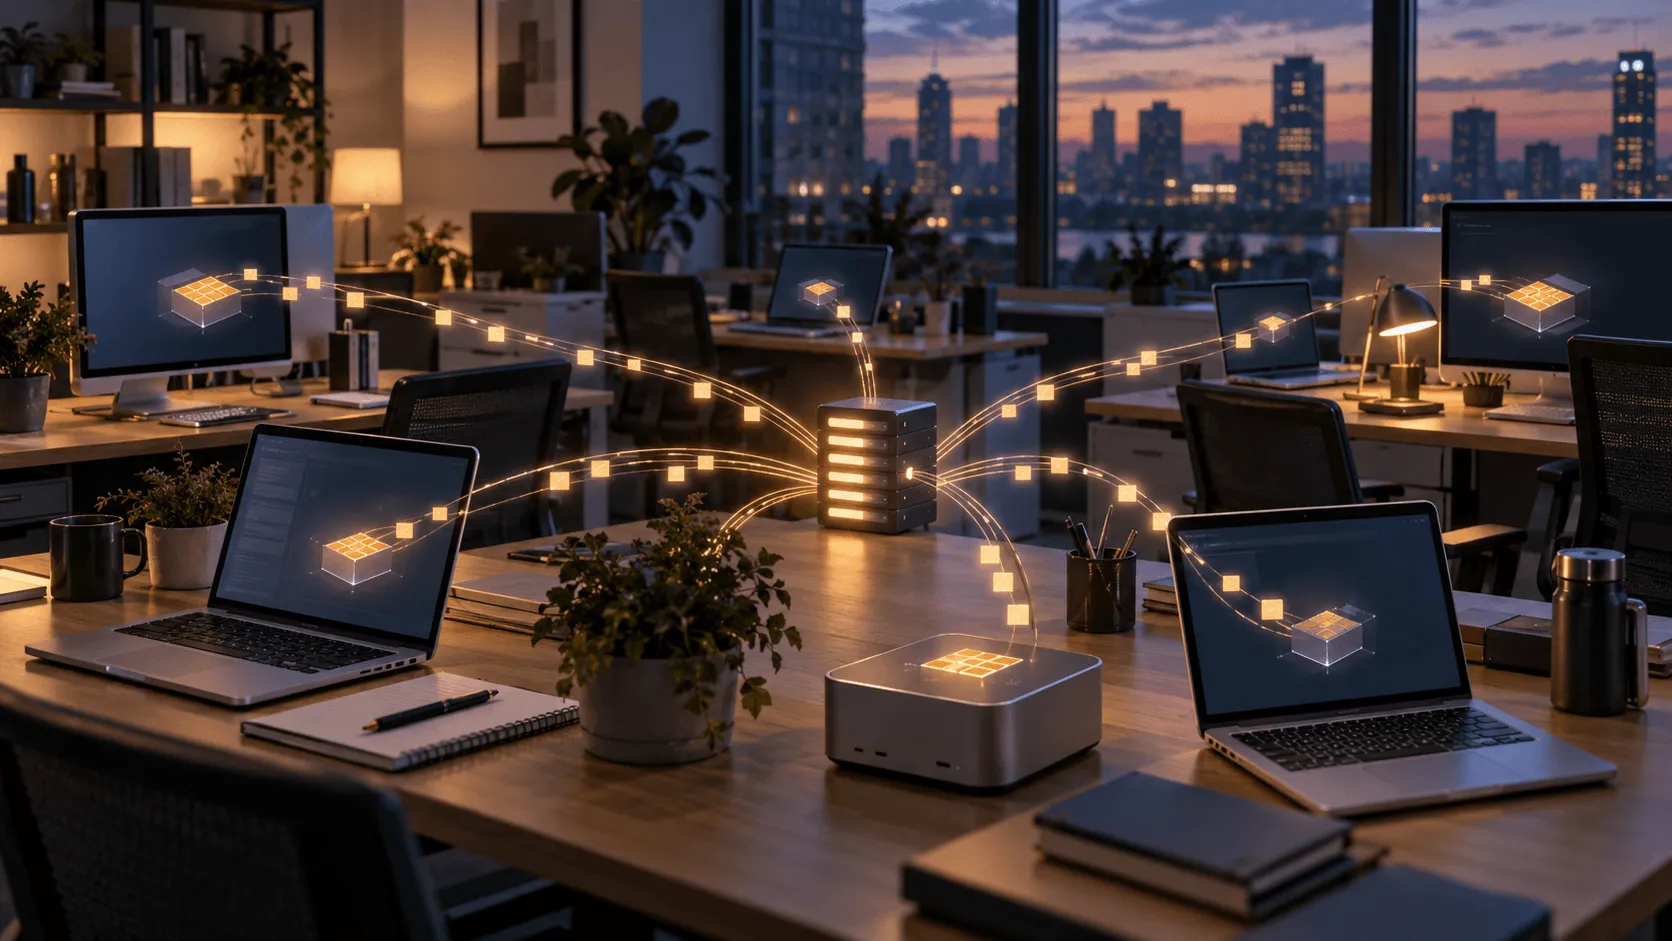
Apple’s Minions system uses idle Apple Silicon Mac GPUs to create a virtual cloud for AI inference, cutting job wait times from over 10 hours to minutes, according to internal research published in a preprint.
Apple’s Minions system transforms idle Apple Silicon Macs into a distributed GPU cloud, enabling large-scale machine learning inference workloads. The research, published in a preprint on October 9, 2026, shows that tasks previously requiring over 10 hours of queue time can now start within minutes by leveraging underused Mac GPUs. The system, developed by Apple researchers including Jianhua Li, Yun Xing, Girisha De Silva, Ryan Flint, Kai Yuan, and Sean Suchter, is described in a white paper titled Minions: A Dynamic and Distributed Virtual GPU Cloud Built on Idle Apple Silicon Devices.
The paper highlights how constrained GPU resources delay access to inference tasks and increase costs, even as powerful Macs with Apple silicon chips sit idle.
How Minions Works
Minions operates by aggregating idle GPUs from macOS devices into a shared platform. Each Mac runs a Minion Executor
that pulls tasks via REST APIs, processes them using the Apple Silicon GPU, and returns results to Amazon S3. If a Mac goes offline, the Minion Watchdog
reassigns the task to another device, ensuring fault tolerance. The system avoids centralized GPU clusters, which are costly and oversubscribed, by utilizing existing hardware. The Minion Server provides the coordination layer, receiving user requests and splitting tasks into subtasks stored in a PostgreSQL database. The Minion Executor runs inference tasks on a Mac’s GPU, uploads results to S3, and reports execution status through the Minion Server, which maintains task metadata in PostgreSQL. The Minion Watchdog monitors this process for failures—such as a Mac going to sleep or losing its network connection—and reassigns tasks if needed.
Users can prioritize jobs through dynamic task binding,
allowing teams to focus computing power on urgent tasks. For example, Slack messages might coordinate which Macs handle specific projects. However, data confidentiality remains a challenge, prompting team- or organization-scoped deployments to isolate workloads. If a Mac stops midway, another machine takes over, ensuring continuity. Minions does not run on dedicated servers in data centers but instead relies on idle macOS devices.
Apple’s internal research describes Minions as a complement to existing centralized GPU facilities. By using idle GPUs, Minions turns underused Macs into a cluster of AI-ready machines. Both the Mac mini and Mac Studio support clustering via Remote Direct Memory Access (RDMA) over Thunderbolt 5, allowing compute and memory to be combined for single AI workloads.
Real-World Impact
Apple researchers report that Minions has been internally tested, reducing GPU queue times significantly. The system does not require new hardware, relying instead on existing Macs. However, electricity costs and hardware wear are not factored into the zero-infrastructure-cost claim. The paper notes that while Minions currently supports inference, future work aims to extend it to distributed model training. The scaling was also organic.
Apple’s approach contrasts with traditional GPU clusters, which prioritize throughput and latency. Minions focuses on hardware availability, making it suitable for scenarios where existing Macs can be repurposed. The system’s reliance on macOS devices also highlights Apple’s broader push to integrate AI workflows into its ecosystem, alongside projects like MLX for large language models. For example, a single Mac Studio offers up to 512GB of unified memory,
and a cluster of four Mac Studios ran Muse Spark Open at over 36 tokens per second,
according to MacObserver. These projects tackle different jobs: MLX focuses on squeezing large models onto desktops, while Minions redistributes idle resources.
The system’s design assumes that interruptions—such as a Mac going to sleep, losing its network connection, or having the executor stopped by users—will occur. The Minion Executor on each Mac sends a heartbeat to the server every five minutes. Unfinished subtasks return to the queue when a Mac goes offline, ensuring no work is lost. Teams can set their own Macs to handle urgent inference jobs first, with non-prioritized work then drawn from a shared queue. This flexibility allows for efficient resource allocation across departments.
Expanding Minions via Federated Networks
While Minions is currently limited to internal use, the research team envisions a future where idle Macs across organizations or even globally could form a shared GPU resource pool. However, security and scalability remain hurdles. The paper emphasizes that secure federated networks would be required to expand Minions beyond Apple’s internal infrastructure. Apple acknowledges that while Minions could theoretically scale globally, it has not yet been announced as a product for ordinary users.
Apple's Minions Turns Idle Mac GPUs Into a Distributed AI CloudApple researchers have developed Minions, an experimental system designed to turn unused GPU capacity across Apple Silicon Macs into a shared computing resource for artificial intelligence.Instead of relying… pic.twitter.com/c0rRUo6Mdb
— https://x.com/tchsignal/status/2110416881551348212
Apple’s Private Cloud Compute (PCC) and its reliance on Nvidia GPUs in Google Cloud highlight the company’s ongoing efforts to balance AI scalability with data security. Minions represents a complementary strategy, using existing hardware to address AI workload bottlenecks without additional capital expenditure. The paper also mentions that the system’s operational evaluation describes its use as a complement to existing centralized GPU facilities. While Minions has been used to support GPU inference workloads across multiple teams, the paper does not state that Apple plans a product built on Minions. It describes a tool Apple teams use internally, with a focus on efficiency rather than commercialization.
The research team acknowledges that while Minions reduces wait times, it does not eliminate costs. Electricity to run the Macs, storage for input data and results, and maintenance of servers and databases all incur expenses. Managing individual machines and handling problems also require staff and time. Despite these limitations, the team argues that Minions demonstrates how existing hardware can be repurposed to improve AI infrastructure efficiency.
More on Apple Silicon Macs
🔴 Apple researchers build distributed GPU cloud from idle Mac devicesApple researchers have developed Minions, a system that aggregates idle GPUs across Apple Silicon Macs to run large-scale machine learning inference workloads. The platform addresses constraints in… pic.twitter.com/DfXxUIGxOx
— https://x.com/NewsTongueX/status/2110047342174859627
🍎 Apple is turning idle Macs into a virtual GPU cloud with its internal 'Minions' system, leveraging Apple Silicon to handle AI inference when dedicated GPUs are scarce. This clever resource optimization highlights how consumer hardware can scale enterprise AI workloads.…
— https://x.com/lordnewss/status/2110336559924888053
Apple developed Minions, a system that makes unused GPU capacity on Macs available for AI applications. dlvr.it/TVvk10 #Infrastructure #AIInference #Apple #GPU #Mac – Follow for more pic.twitter.com/ZawFnyFdyr
— https://x.com/techzine/status/2110297175775433090