Frontier artificial intelligence models are doubling their autonomous completion horizons roughly every 110 days on verifiable programming work, according to an evaluation update published on November 20, 2026, by Model Evaluation and Threat Research.
Time Horizon Growth Rates
The nonprofit evaluation organization released its combined Time Horizon 1.1 and Time Horizon 2 findings, tracking how long a human expert’s task takes before an AI system can finish it with a 50% success rate. Across the tested checkpoints, these 50% time horizons are doubling every 3.61 months, or approximately 110 days, with a 95% confidence interval ranging from 2.08 to 4.94 months, CASRAI reported.
The updated evaluation analyzed 15 major model checkpoints from generations including OpenAI’s GPT-6 Astra, GPT-5.6 Sol, and Anthropic’s Opus 5.5. On verifiable software engineering challenges, frontier models demonstrated time horizons reaching up to 27 hours of human-equivalent labor, frequently matching or outperforming skilled human engineers on self-contained programming assignments.
Flashback to June 14, 2024. At the time, frontier AI models have zero fluid intelligence. They score around 5% on ARC 1. They can't reliably add two numbers. They make laughable logic errors every other prompt. Reasoning models don't exist. Coding agents don't exist. Claude Code…
On tasks such as MirrorCode, where autonomous agents reimplement existing software by checking their work against a comprehensive test suite, Opus 5.5 successfully resolved 77% of medium to large software programs. Human experts typically require weeks or even months of independent labor to complete those specific coding programs on their own.
Coding Pacing Versus Research Judgment
While coding and optimization capabilities continue an exponential climb, open-ended research tasks and strategic decision-making remain a persistent bottleneck. The expanded Time Horizon 2 suite contains 36 tasks divided into 12 families, featuring eight verifiable categories alongside four conceptual reasoning and qualitative evaluation families.
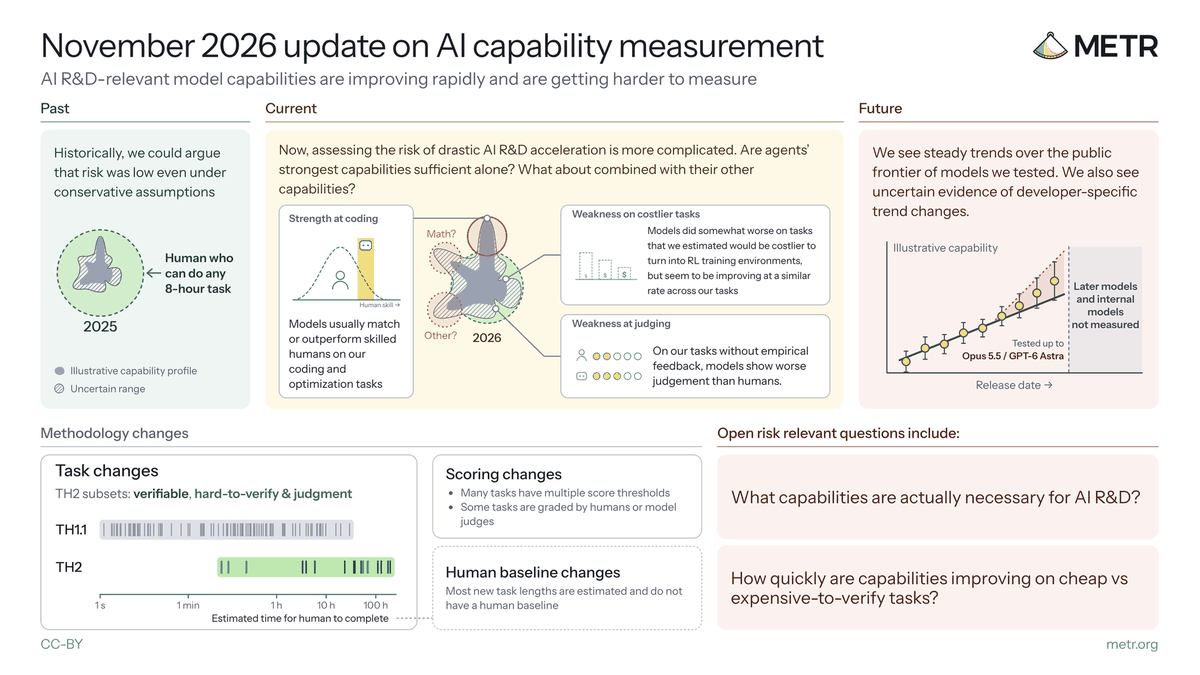
On verifiable tasks alone, the estimated doubling time sharpens to 1.65 months, with a 95% confidence interval spanning from 0.79 to 3.99 months, though METR cautioned that this faster rate could reflect task composition or development selection rather than broad acceleration. Conversely, tasks requiring open-ended research judgment—such as designing evaluations or assessing philosophical arguments—showed models lagging behind expert human performance.
Even so, the newest models show measurable improvement on difficult qualitative metrics. Some systems achieved what researchers designate as “borderline above the bar” performance on evaluation design tasks, advancing from “clearly below the bar” ratings recorded a year prior, MIT Technology Review reported.
We've been working on understanding model capabilities beyond what our prior time horizon tasks could capture. Today we’re sharing a research update. We find that AI R&D-relevant capabilities are improving rapidly and are getting harder to measure. pic.twitter.com/Z1iXyIjERy
Najoung Kim, a linguist and computer scientist at Boston University, said that the observed improvements provide informative signal for the current moment, though predicting how those capabilities will extrapolate moving forward remains challenging.
Evaluation Methodology and Specialist Costs
Calibrating the new test suite required extensive human input and structured qualitative grading. Direct human baselines informed only 9% of the human-duration estimates used in the benchmark, while the remainder relied on researcher estimates, Daily Artifact reported.
Specialists evaluating the tasks were compensated between $200 and $350 per hour and utilized Sonnet 5 for implementation support. Quantifying hard-to-verify tasks remains an inherent obstacle for safety organizations attempting to track automated research capabilities.
By their nature, hard-to-verify or judgment-laden tasks are much harder to study, and especially to quantify.
Matt Putz, technical staff member at METR
Implications for Artificial Intelligence Acceleration
The growing gap between rapid code automation and stagnant research judgment highlights the central technical barrier facing autonomous systems today. While models can execute structured, well-specified programming objectives efficiently, they struggle to distinguish between productive scientific avenues and dead-end pathways.
We're sharing new data on how AI is changing research at OpenAI. We find researchers' AI use continues to rise exponentially, and agents are completing longer tasks, but human involvement remains central in research. Researchers are also spending more time on safety and…
Model Evaluation and Threat Research was founded in December 2023 when ARC Evals, the evaluation division of Paul Christiano’s Alignment Research Center, was spun off into an independent 501(c)(3) nonprofit based in Berkeley, California. Its CEO is Beth Barnes, a former alignment researcher at OpenAI who left in 2022 to form ARC Evals.
The institute evaluates frontier models’ capabilities for long-horizon, agentic tasks and has conducted pre-deployment evaluations for OpenAI’s o3, o4-mini, GPT-4o and GPT-4.5, and Anthropic’s Claude models. Following the 2026 OpenAI agent cyberattacks, OpenAI invited METR to conduct an independent investigation; it published its report on August 26, 2026.
Nevertheless, the organization maintains that current public evidence is insufficient to rule out drastic artificial intelligence research and development acceleration over the next couple of years. METR continues its ongoing safety assessments under established evaluation agreements as developers prepare next-generation architectures for release.